Why Managed Runtime Platforms Change the Governance Calculus for Claude Code and Codex at Team Scale
Managed runtimes give teams the governance that coding agents require at scale.
A managed cloud platform for running Claude Code and Codex at team scale must provide isolated execution, real-time budget enforcement, attributable session logs, and version-controlled agent configuration. With these controls, teams can use coding assistants as governed engineering infrastructure without having to manage cloud instances. Governance must be enforced by the runtime wherever the agents run, relieving each developer of that responsibility.
Why a single developer running Claude Code looks nothing like a hundred doing it simultaneously
One developer means one invoice and one blast radius. That developer can keep track of the agent’s access, usage, and configuration personally. With fifty or a hundred engineers, people usually start using agents before platform engineering or security gets involved. A few developers get results and tell teammates. By the time the organization considers governance, a large cohort may be running agents with default settings and no shared guardrails.
A provider invoice cannot establish which team, project, or engineer drove spending, while unrestricted model access lets routine tasks consume the most expensive tier. Finance sees the result after the billing period closes. Without a verifiable record of who sent what to which model and when, security teams also lack evidence needed for SOC 2, HIPAA, GDPR, and ISO 27001 review.
Claude Code further expands the scope of that exposure. It operates in the developer’s terminal with the local user’s permissions, reading files, executing shell commands, and connecting to MCP servers and external APIs. Without deny rules that block it, the agent can also access .env files, SSH keys, and ~/.aws/credentials.
How Claude Code and Codex differ architecturally, and why that changes what governance must cover
Claude Code’s local execution model gives it the developer’s filesystem and network access. A compromised .claude/settings.json, hook injection, or malicious MCP tool response can redirect traffic and expose prompts, responses, and API keys. Local permissions become the agent’s operating boundary. For a platform team, governing this model means imposing isolation that the tool does not provide by default.
Codex’s cloud execution model starts from a different boundary. It clones the repository into an isolated sandbox, runs tests, and creates a pull request, with internet access disabled by default during agent execution. Each task receives its own ephemeral compute environment. With that default isolation, the agent cannot reach external services, databases, or secrets outside the repository while it runs. Limited or unrestricted internet access can be configured, so the security posture depends on the selected access policy.
The governance requirements are consequently not symmetric. Claude Code needs controls over local access, spending, and attribution, while Codex’s native sandboxing already sets a boundary for where it can run. Sandboxing does not establish organizational budgets or a complete audit trail. A team deploying both needs a common governance layer that respects their different execution models while applying consistent identity, cost, and evidence requirements.
Why identity is the first control to establish, before any spend or permission policy is meaningful
The first deployment action is to establish enterprise-controlled identity before broad rollout. A spend cap needs an accountable owner, a permission policy needs a subject, and an audit event needs a person or trigger behind it. Personal accounts break that organizational chain of control. They leave the enterprise without centralized access revocation, usage visibility, or an attributable audit trail.
For Claude, the practical starting point is SSO configuration in the Claude Admin Console. Requiring SSO for Console ties administrative authentication to the IdP, while requiring SSO for Claude prevents personal-account fallback. Domain capture automatically brings people who sign in with a corporate email address into the enterprise workspace. IdP groups can then map to Primary Owner, Admin, and scoped developer roles at provisioning time.
At the API layer, sending traffic through a central gateway via ANTHROPIC_BASE_URL gives teams one place to enforce rules. The gateway gives out virtual keys tied to budgets, rate limits, model allowlists, and routing rules while keeping the provider key hidden. Revocation becomes one gateway operation, eliminating the need to search for copied credentials. This credential hierarchy connects a request to an enterprise-controlled identity and the policies attached to it. Identity is therefore a prerequisite for spend and permission enforcement.
How spend becomes uncontrollable without real-time enforcement, and what enforcement actually requires
Agent spending compounds through repeated context loading and execution loops. System prompts and repository maps account for much of the bill for producing code. Unrestricted model selection adds another source of avoidable consumption when routine tasks use the most expensive tier. A dashboard records these choices after they happen. It cannot prevent the next request from consuming an exhausted budget.
Real-time enforcement requires a hierarchy running from organization to team to individual developer to virtual key. Each level has an independent budget, and a request must pass every applicable limit. Either a team cap or a developer cap can block subsequent requests before they incur further cost. Daily, weekly, monthly, and annual reset windows replace arbitrary hard stops with controls aligned to budgeting periods.
Routing and caching address consumption before a cap is reached. Gateway routing policies can assign lightweight tasks to cheaper model tiers, while semantic caching serves cached responses for semantically similar prompts. Neither depends on developers remembering a cost policy. Anthropic’s Team and Enterprise plans provide built-in spend analytics and caps as a baseline, with a gateway supporting more complex attribution needs. That attribution is the precondition for a useful budget conversation, because finance needs to know which team drove a cost before deciding how to allocate it.
Why the permission-bypass risk is the single most exploitable gap in a Claude Code deployment
Identity and budget controls do not make local tool permissions enforceable. Without disableBypassPermissionsMode, a developer can invoke Claude Code with --dangerously-skip-permissions and bypass its configured permission checks. The permission and tool-call controls that follow are then rules the agent can ignore. An enterprise can have centralized authentication and spending limits while still leaving the agent’s local actions insufficiently constrained.
Managed settings must therefore be resistant to tampering. Server-managed settings, available in beta, deliver configuration from Anthropic’s servers at authentication and are convenient for BYOD environments. Their enforcement remains client-side, however, and someone with sudo access can tamper with them. Endpoint-managed settings delivered through MDM tools such as Jamf, Kandji, or Intune provide stronger OS-level protection. Their managed locations include /Library/Application Support/ClaudeCode/managed-settings.json on macOS and /etc/claude-code/managed-settings.json on Linux.
MCP access adds another boundary to this policy. Without centralized governance, developers can connect to servers whose tool descriptions attempt to alter Claude’s behavior. Retrieved documents, web pages, and API responses can also contain injected instructions. An MCP Gateway replaces separate developer allowlists with centralized tool access control, guardrails, and invocation auditing. Managed settings and tool policy are thus runtime infrastructure, while their audit records provide evidence of how that infrastructure operated.
What full observability of agent sessions actually means, and why execution logs alone don't satisfy it
Execution observability records each tool call, diff, and shell command, together with its target, time, and identity. It establishes what the agent did. Intent observability connects those actions to the initiating prompt, reasoning tokens, and decision chain within the session. A command log on its own cannot show those links. Recording API request and response pairs without their relationship to the broader session leaves a similar gap.
This distinction changes the scope of an audit. A diff must remain linked to the prompt that produced it rather than exist only as an isolated version-control artifact. Every tool invocation needs attribution to a person or trigger. Session-scoped credentials must also be revoked on completion. Their lifecycle then matches the actions they enabled, rather than extending beyond the session represented in the audit record.
The EU AI Act, NIST AI RMF, and Singapore’s Model AI Governance Framework for Agentic AI align directionally on accountability, behavioral transparency, and human oversight. Transparency and logging are distinct obligations, however. A session trail supports accountability, but it does not replace notifying users that they are interacting with an AI agent. Operating agents in production requires both technical records and controls suited to the applicable obligation.
Treating agent configuration as code, not as per-developer setup, is what makes governance scale
Files such as CLAUDE.md, AGENTS.md, and agents.yaml separate instructions about agent behavior from the machinery that runs the agent. Changes can be reviewed and linted like other infrastructure code. The configuration is no longer an undocumented property of a developer’s machine.
The division between universal and tool-specific instructions prevents silent misconfiguration. AGENTS.md holds shared build commands, test instructions, conventions, architecture notes, and security boundaries for agents that support the format. CLAUDE.md holds Claude-specific skills tables, context-loading directives, subagent delegation patterns, and hook-based context injection. Other agents may ignore or misinterpret those instructions.
A validation step on every push catches stale paths and renamed scripts before they misdirect agent behavior. In headless CI execution, the governed configuration supports agents that pre-screen reviews, generate tests, update documentation, and handle routine fixes. A person must check the results before merge. Configuration-as-code turns a collection of individual setups into an engineering capability whose instructions can be inspected, changed, and applied consistently.
How can a team run Claude Code and Codex without managing cloud instances?
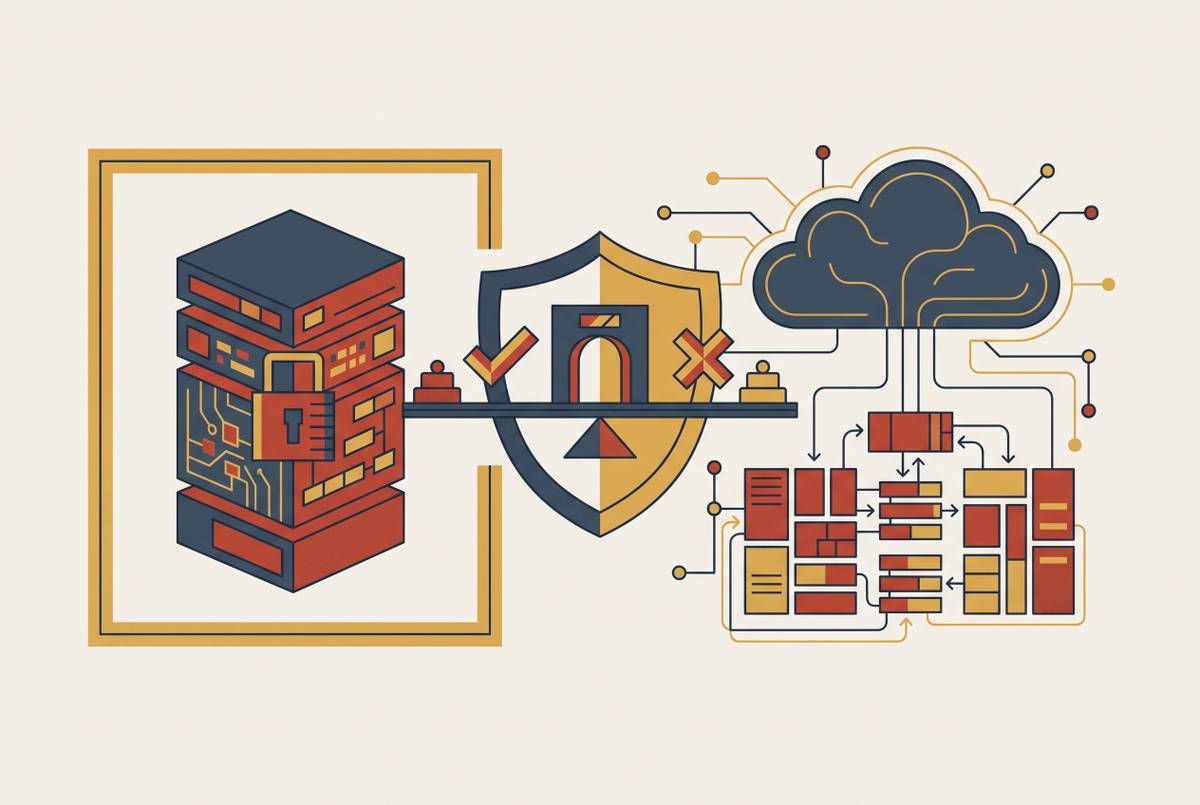
Local machines, organization-hosted VPCs, and managed cloud platforms distribute governance work differently. When agents run locally, monitoring and policy enforcement are spread across each developer’s own environment. Credentials and configuration remain difficult to govern consistently. Moving execution into an organization-hosted VPC can provide full logging, auditing, access controls, and IAM integration, but the platform team must build and maintain those capabilities.
Self-hosting can therefore achieve strong governance. It cannot remove the engineering and operational work required to assemble it. A managed runtime changes that responsibility by supplying isolated session execution, credential lifecycle management, budget enforcement, and attributable logging as infrastructure. The distinction is whether the organization must implement the integration of these controls itself.
For a team seeking Claude Code and Codex together without managing instances, the decisive criteria are concrete. Each session needs an isolated sandbox and freshly minted credentials that expire on completion. Budgets must stop spending as well as report it, and logs must link tool calls, diffs, and token use to the person or trigger behind them. Repository-defined YAML configuration must govern the agents running in that environment. A managed platform that supplies all these properties makes the agents-as-code pattern operational without a separate bespoke governance system.
The governance calculus in practice: what changes when platform teams treat agents as managed infrastructure
With the runtime governed and infrastructure configuration handled by the platform, engineers work through prompts, pull requests, and CI triggers. Agents can produce product code, tests, release tooling, documentation, evaluation harnesses, and review comments. Failures show where tools, guardrails, or documentation are missing. The team can address those gaps through changes to the shared engineering system, eliminating the need to repair individual setups.
The AI Gateway handles authentication, model routing, rate limiting, budget enforcement, and request-level observability. The MCP Gateway governs tool access, guardrails, and invocation auditing. Because those controls operate at the infrastructure layer, development teams do not need to implement them independently. An audit can draw on attributable records of sessions, credentials, tool calls, and diffs, eliminating the need to reconstruct activity after the fact.
The rollout should follow the same dependency order. A small team can validate managed settings, identity controls, spend caps, and observability before broader adoption begins. Expansion then extends an established governance layer rather than retrofitting controls around uncontrolled usage. That is the practical change managed infrastructure makes possible. Platform teams can move from asking how to control agent execution to deciding what to build with it.