Hard Budget Caps for LLM API Spend in Agent Pipelines
Agents need hard spending caps enforced before API calls leave.
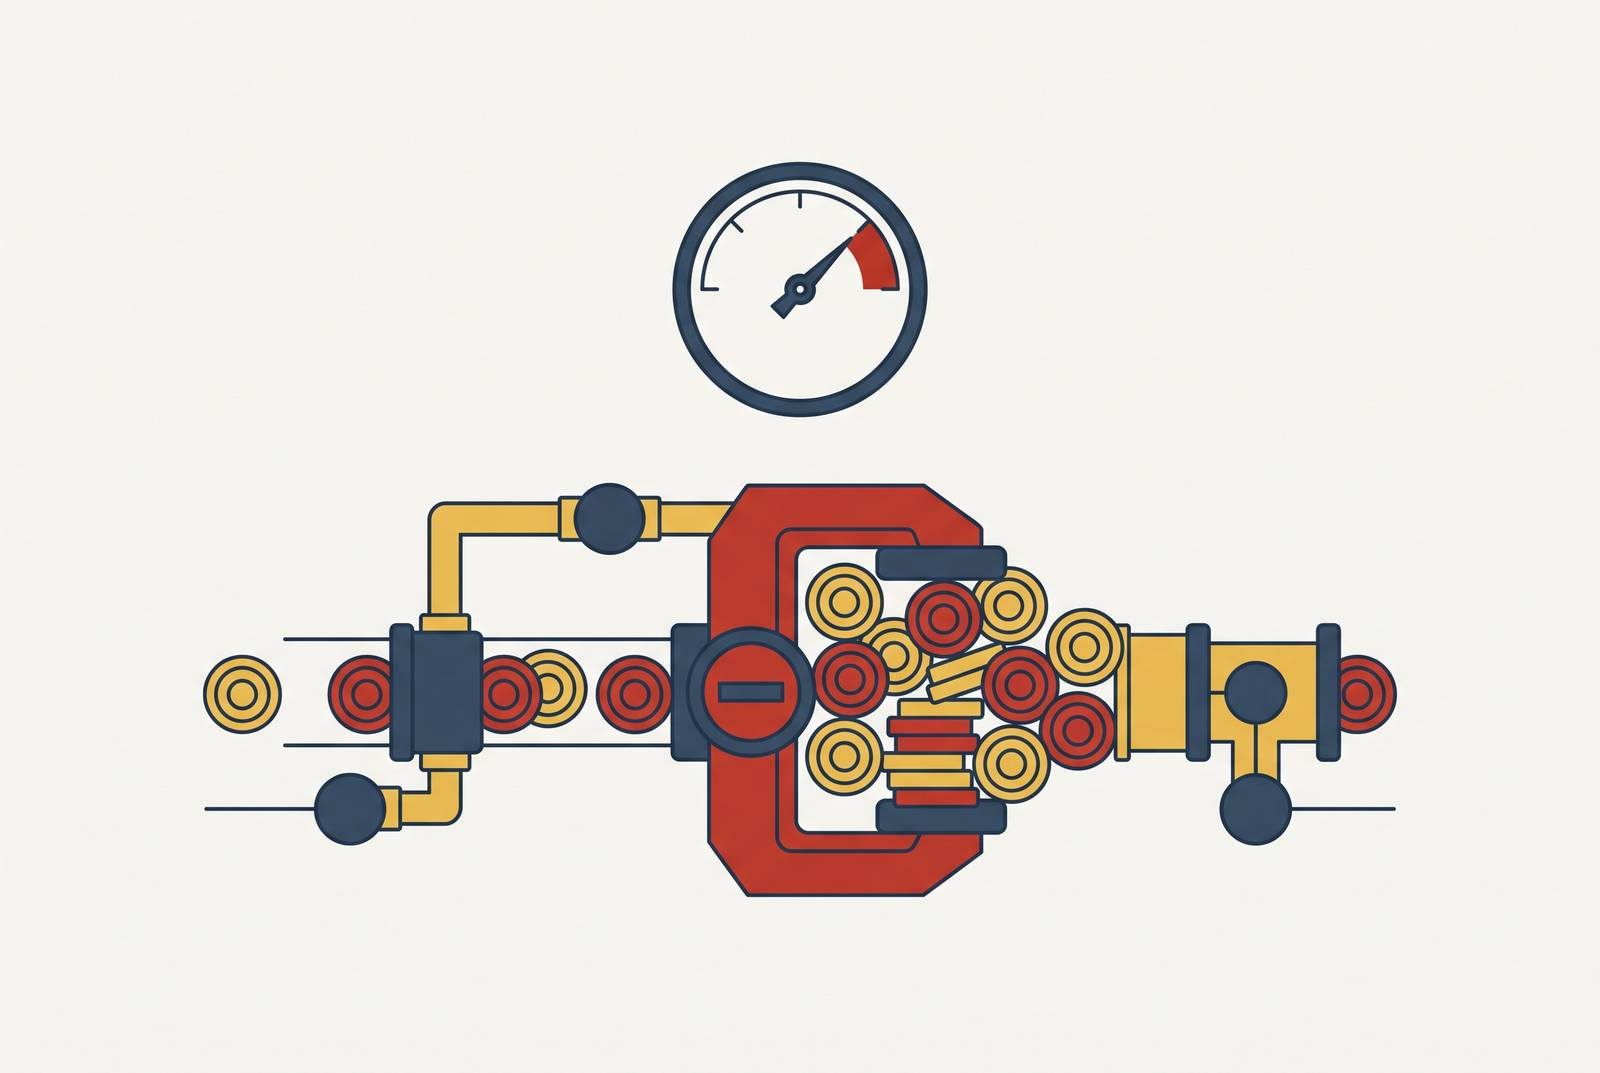
Hard budget caps for LLM API spend in agent pipelines must block requests before they leave, using a shared atomic counter. To stop AI coding agents from running up unexpected bills mid-session, production systems need layered limits across sessions, developers or agents, and time periods. Alerts support that control stack, but they cannot enforce a ceiling.
Why agent pipelines break the assumptions that budget alerts were built on
Budget alerts assume spending is slow enough for a person to step in after an alert arrives. Agent pipelines break that assumption because they consume tokens autonomously and asynchronously, often without anyone watching. A single task can generate orders of magnitude more tokens than a chatbot interaction because each step re-feeds the accumulated context. Consumption therefore compounds with task depth rather than staying close to the cost of the first call.
Retries make that pattern more dangerous. A failed tool call adds its failure to the context, so the next attempt can cost more than the last without bringing the task closer to completion. Unless code enforces a stopping point, the loop has no natural financial boundary. In one hobby-project incident, an agent created duplicate CloudFormation stacks on every error and generated a four-figure bill in under a day, which AWS later partially reduced. That was infrastructure spending rather than token spending, but it illustrates the tempo of autonomous failure.
Billing lag also adds to the time between spending and action to stop it. Providers can take up to two days to report usage charges, and charges accrued before billing is disabled are still billed.
Why alerts fail even when they fire correctly
An alert that fires at 3 a.m. on a Saturday and reaches no one in time has not malfunctioned. It has sent a notification, which is exactly its job. The missing action is enforcement, since the alert still requires someone to interpret it and stop the workload. A hard cap blocks the next API request on its own, without waiting for a person to act.
An on-call rotation shortens that response time but does not remove it. An agent making dozens of API calls per minute can compound spending while an engineer finds a terminal and identifies the process to stop. Batch jobs, CI pipelines, and background tasks make that gap especially important because their execution is not tied to someone watching Slack. The distinction is therefore structural. Alerts can warn that a budget is running low, but they cannot guarantee that spending stops at its boundary.
Why application-layer spend checks fail in distributed agent systems
A spend check before each LLM call seems to close the gap, but checks that run on their own cannot enforce a shared ceiling. Two processes can read the same counter while it still shows headroom, each decide that its request fits, and both go ahead. Together, they can spend more than the limit even though each process seems to have made a valid choice. The defect is shared-state coordination.
The same weakness spreads as services multiply. A new microservice remains unprotected unless its developer includes the check, while a loop can pass individual call checks even as cumulative consumption becomes excessive. Multi-tenant applications also need per-customer state they can trust across those execution paths. Prompt instructions are weaker still, since telling an agent to stop at a spending threshold gives it a suggestion.
Centralizing the decision removes the dependence on each process having an adequate local view. For example, platforms such as Ellipsis run agents in isolated sandboxes with a single atomic enforcement point for budget caps. Sessions check against the same shared counter before an API call, regardless of how many are running or where they were triggered.
Where enforcement must actually live — the proxy layer and pre-request blocking
Every agent must go through the enforcement point to reach the LLM API. A proxy or gateway in that request path can apply one budget decision across services, workers, and agents, backed by a shared atomic counter. It is both centralized enough to coordinate concurrent requests and close enough to execution to stop the next call.
The timing matters as much as the location. Blocking a request before it leaves prevents input tokens from being billed for a call that would exceed the budget. Checking after the response arrives cannot undo consumption that has already happened. The local meter must therefore govern admission to the API rather than wait for the provider’s invoice to reveal an overrun.
Ellipsis applies spend limits at session start and at each request boundary, with credentials minted fresh for each session and revoked on completion. The decisive criterion for any implementation is the same. A limit must stop the request in the path where spending begins.
The three dimensions a production budget cap must cover — session, developer, and time-period
Even with a centralized gateway, limits must cover the ways spending can get out of control. One global monthly cap cannot tell a runaway session apart from normal work across a team. Production enforcement therefore needs three dimensions, which are the session, the developer or agent, and the time period. Each closes a gap the other two leave open.
A session ceiling limits the tokens or dollars available to one execution and terminates it immediately when reached, even before the next safe checkpoint. Its purpose is to stop runaway retries before they consume a wider allocation. The recommended sizing approach is to calculate the worst-case single-session cost and set the ceiling at a multiple of expected normal cost. That leaves room for work that needs to spend more while still capping what a failure can cost.
A per-developer, per-agent, or per-key cap then limits how much damage can spread across sessions. A compromised or misconfigured agent can consume only its own slice of the account’s allowance. A stolen key constrained to that slice can trigger a targeted alert before reaching the organization-wide ceiling.
Daily and monthly caps keep spending from drifting upward over time. Many sessions can each stay below their own ceilings while together spending more than the team’s budget. Across a large engineering team, CI/CD pipelines can have runs that each stay within budget but add up to spending that needs FinOps governance.
Budget caps as YAML-driven configuration in agents-as-code pipelines
Budget policy becomes reviewable and auditable when it lives in the repository with the agent definition. A limit set only in a dashboard is outside pull-request review, so a configuration change can slip past the engineering workflow without notice. By contrast, a budget increase committed as configuration requires a pull request and leaves a change attributed to a person. Spend policy then follows the same review process as other changes to the agent.
YAML expresses that policy without scattering enforcement logic through application code. An agent configuration can have fields such as daily_limit and per_task_limit, and the enforcement layer enforces the limits set there. Ellipsis implements this agents-as-code pattern through repository-managed YAML definitions that include budget controls. The important property is not the file format alone, but the connection between reviewed policy and enforced behavior.
Multi-agent pipelines also need hierarchical budget inheritance. A parent task allocates fixed sub-budgets to the agents it spawns, preventing one subtask from consuming the full parent allocation. That hierarchy keeps spending traceable to the workflow that triggered it.
Cost attribution as a prerequisite for enforcement — tagging every request at the call site
A shared counter is useful only if each request reaches the right counter. For per-developer and per-agent caps to work, the enforcement layer must know who used the tokens. Attribution must therefore travel with the request from the call site, rather than be reconstructed after the invoice arrives. This is an input to enforcement.
The minimum useful metadata includes user_id, agent_run_id, feature or agent name, model, deployment, and prompt_version. These tags answer different questions about the same call. The agent_run_id brings all the steps of one run into a single rollup, while deployment keeps staging separate from production. The prompt_version shows how prompt changes affect cost traces, so their effect is not lost in total spending.
Without that context, distinct failure modes collapse into the same invoice increase. A runaway loop loses the fingerprint of each run, retry tokens can hide behind a successful response in the log, and context bloat can raise the average cost of a session before total spending is clearly too high. Post-hoc log parsing cannot recover information that the application discarded. Tagging at the call site keeps attribution attached through downstream rollups and alerts, so the budget boundary applies to the workload it was intended to constrain.
Budget caps as a security control, not just a FinOps hygiene measure
Unlimited token consumption is also an attack surface. An agent manipulated into repeated or unnecessary work can burn its operator’s API budget, making the hard cap both a defense against denial-of-wallet and a cost optimization. OWASP designates this broader category as “Unbounded Consumption” in LLM10:2025, with denial-of-wallet as one attack pattern within it. Under that threat model, a warning that spending has increased is not an adequate boundary.
The cap must sit outside the agent’s trust boundary because a compromised agent cannot be trusted to follow its own rules on spending. An application-layer check that the agent can reach or bypass does not provide the same separation as infrastructure enforcement. A proxy-layer limit constrains the agent regardless of its reason for making another request. That changes the test for adequacy from whether the control usually helps to whether the agent controls the mechanism that stops it.
NIST’s Center for AI Standards and Innovation started its AI Agent Standards Initiative in February 2026. That is a directional governance signal, since extensions to the existing NIST AI RMF 1.0 remain in development. Session isolation, scoped credentials, and attributable activity fit this broader accountability posture. In Ellipsis’s design, every tool call, diff, and token is logged and attributable, placing budget enforcement within a governance layer.
How to stop AI coding agents from running up unexpected API bills — what to configure first
Start with a per-session token or dollar ceiling at the proxy layer, backed by an atomic shared counter such as Redis or an equivalent. This stops the worst-case retry loop before it can compound across an unrestricted session. Set the ceiling at a multiple of the expected normal session cost that leaves room for heavy work. For budget enforcement, graceful shutdown cannot mean allowing more billable work until the agent decides it has reached a convenient checkpoint. The session must terminate when the ceiling is reached.
Next, set per-agent daily_limit and per_task_limit values in repository-managed YAML, then add the wider time-period ceilings. When one agent exhausts its allocation, block that agent’s LLM calls while allowing the rest of the pipeline to continue. Add request attribution before treating developer- or team-level enforcement as operationally complete. In particular, agent_run_id, user_id, and feature tags connect the request to the limits intended to govern it.
Then pair alerts at defined budget percentages with the hard caps. These notifications give early warning during normal operation, while blocking remains the backstop when no one responds. Finally, check the precise control the provider offers rather than assuming that every setting called a budget is a cap. Anthropic offers per-workspace spend limits that stop API usage until the next cycle, while Google Cloud distinguishes alerts-only budgets from spend cap budgets that pause new usage. OpenAI brought hard spend limits back to all API Platform accounts in July 2026 after it had replaced them with notifications.
A managed platform such as Ellipsis provides session isolation, scoped credentials, and budget controls as ready-made infrastructure. Every session starts with a set budget, every request goes through enforcement, and policy changes go through review. That is governance by default, with alerts supporting a ceiling that does not depend on anyone being awake.