Chargeback Models for AI Agent Spend Across Engineering Teams
Hard budget caps and layered metering prevent AI agent spend from spiraling across your teams.
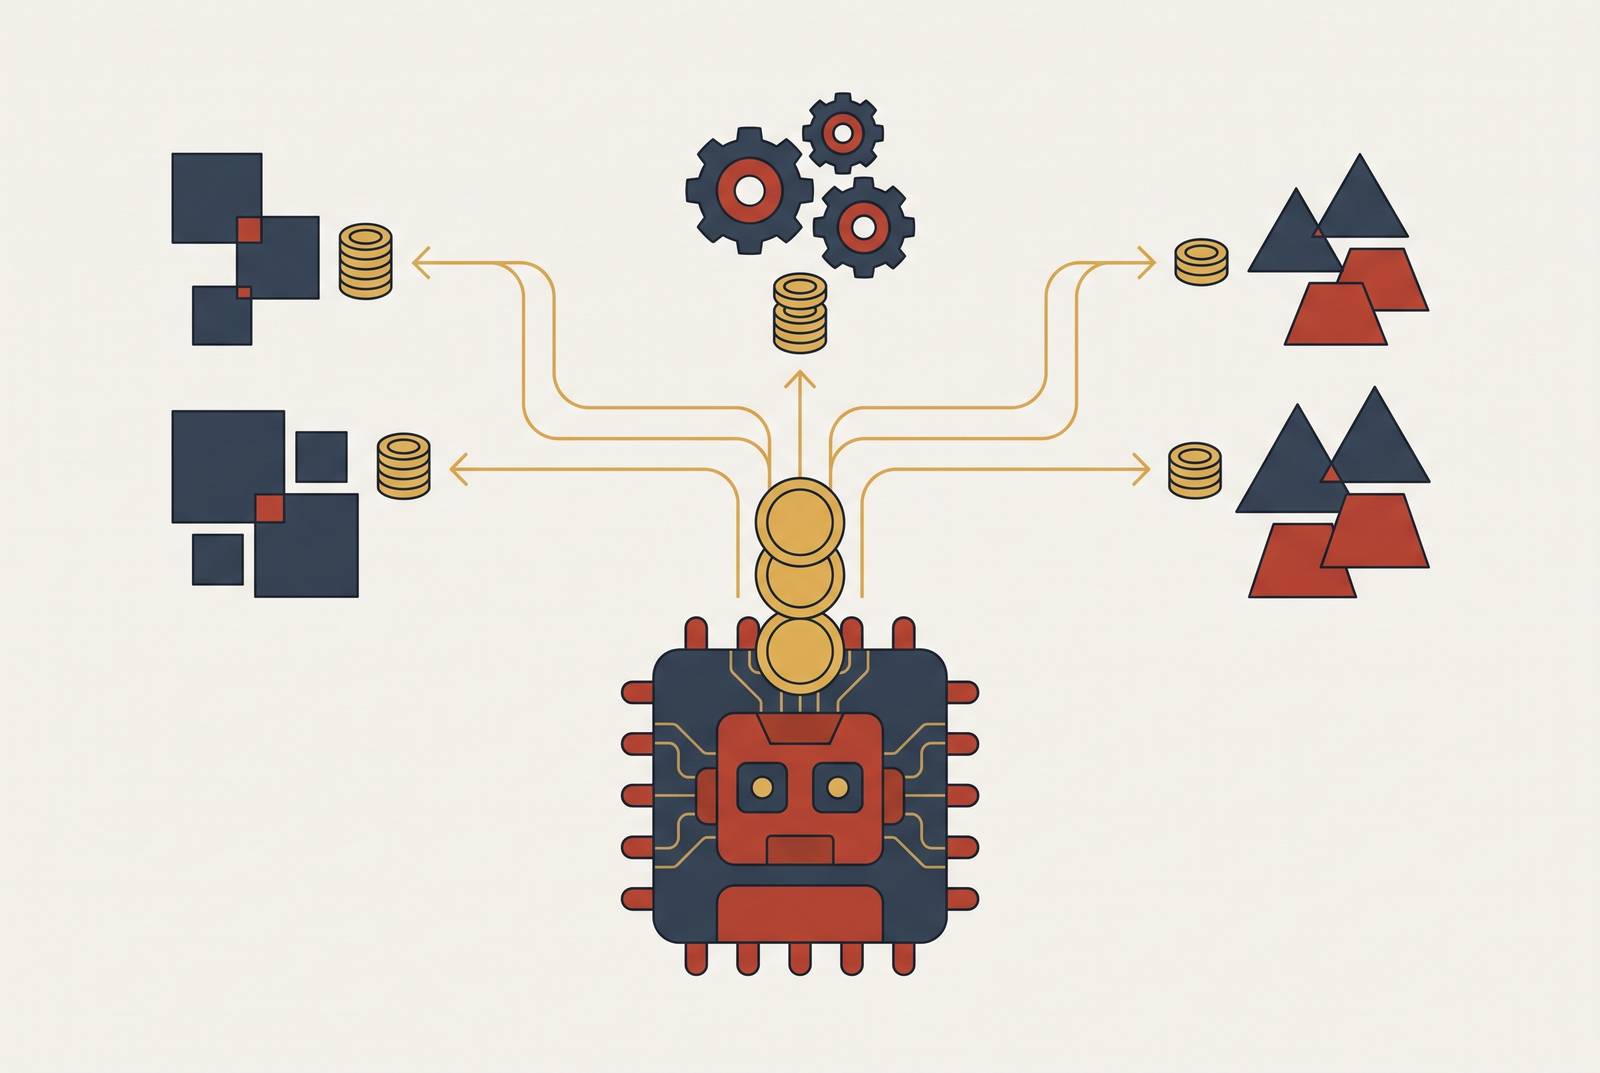
Chargeback models for AI agent spend need a layered control stack, including call-time metering, clear ownership, and hard budget caps at the session, developer, and time-period levels. To stop unexpected API bills mid-session, the cap must prevent execution from continuing. Allocation then determines who pays, while session-level enforcement limits what can be spent.
Why AI agent spend has a different cost structure than any infrastructure bill you have managed before
An autonomous coding agent consumes resources through both its behavior and its provisioned capacity. A seat license has a flat price, and a cloud instance can be provisioned and tagged. An agent’s consumption instead depends on context length, output length, retry paths, tool-call chains, and model routing decisions. Those variables are not fixed when the infrastructure starts, so a resource budget cannot by itself bound the cost of the work.
ACEM identifies token consumption as a highly variable cost driver. Its magnitude depends on agent autonomy and the pricing model, ranging from negligible to exceeding human labor cost for the same task type. The model’s Revision Factor captures the overhead of rejected outputs and retries, while its Context Factor captures context growth across a session. Both can multiply spend without any change to the underlying infrastructure.
Consequently, one heavy agentic session can consume orders of magnitude more tokens than a light session on the same team in the same hour. Headcount and seat averages conceal that variation. Generic cloud infrastructure can support a prototype, but production agentic systems need spend governance at the session level. The financial control must follow the agent’s activity because provisioning alone does not determine its bill.
What you actually need to meter before any allocation model can work
Attribution starts with the agent. Keys are shared, rotated, and reused, so a key cannot serve as a durable record of ownership. Every agent call should instead pass through a gateway that stamps the request with the tag chain, namely org, team, project, and agent. No service should call a provider SDK directly, because that bypass creates spend without the ownership record needed later.
In that record, input and output tokens need their own meters because their prices differ. Model and version must also be recorded so that routing decisions remain visible. Cached and uncached calls need to be tracked separately because cache hits change the effective cost per call. Agent runs and tool calls tie those measurements to the work done, including cost per PR and cost per resolved ticket. ACEM also treats human involvement as a cost dimension, so oversight and correction time should be tracked even when it is not charged back.
These meters need more than the cloud resource tags already in place. One model endpoint may serve every team, and the same prompt can cost different amounts as context, output, and cache state change. Provider consoles also report usage differently, which fragments the raw record. When one agent invokes a shared retrieval agent that calls a model, the spending team and the benefiting team may differ. The instrumentation must preserve that action chain before an allocation rule can decide who owns the cost.
How to organize spend into a hierarchy that maps every token to an owner
Metered events become an attribution system when they roll up through a defined ownership hierarchy. The org tier holds the total spent on model API calls in each period, which is the top-line number the board sees. The team tier supplies the unit of accountability, with a budget and trend line for each team. The project tier separates initiatives with different economics, while the agent tier exposes the individual run patterns behind spikes. An unbounded summarization loop belongs at that lowest tier.
The hierarchy should show cost in units that teams can use to plan. Cost per PR reviewed, cost per ticket resolved, and cost per migration validated show what the organization gets for its money. Cost per million tokens shows how much is used but leaves out what work gets done. ACEM maps existing project-scoping data, including Use Case Points, Story Points, and Function Points, to estimated token consumption, allowing forecasts to use sizing data teams already produce.
Shared costs need their own place above the team tier. Pre-paid GPU capacity, foundation model subscriptions, and the governance platform should not disappear into averaged team rates. Publish the shared-cost allocation rule before the first report and display the unallocated residual as its own line. With repository-based YAML agent definitions and retained tool-call logs, Ellipsis illustrates the configuration and observability foundations for this structure. The call-time ownership tags remain essential, because configuration and logs alone do not establish the full cost allocation chain.
The five chargeback model variants and what each one demands from your data
Cost pass-through charges each team for the agent activity that its meters record. It is straightforward and accurate where spend has a direct owner. Its limit is shared infrastructure or shared agent services, where there is no single team cost to pass through. This model fits instrumentation that reliably separates direct consumption from the shared remainder.
Per-task flat rates make costs easier to plan for, but bills no longer match exact consumption. A fixed price per PR reviewed, ticket resolved, or migration run needs enough past data to reflect what the work really costs. A rate set too low causes the platform to absorb losses, while an inflated rate can encourage teams to batch tasks. ACEM’s Revision Factor and Context Factor help estimate the retry and context overhead behind that fixed price.
Usage-tier models put teams in light, moderate, or heavy bands, with the same charge for each team in a tier. They need dependable aggregate usage and clear band boundaries. Teams can know their tier before the month ends, reducing disputes. The trade-off is less precision because different levels of consumption within a band receive the same charge.
Outcome-based models charge for the value of work done, including merged PRs or resolved incidents. They require agreement on what counts as an outcome and measurement at the agent level. Their pricing must also survive months when task mix reduces outcomes without indicating inefficiency.
Hybrid models leave foundation costs in a central budget and charge incremental use-case costs to the commissioning team. Governance, model subscriptions, and training can stay central while directly attributable consumption is charged back. This approach needs a written rule for which costs are charged and which are shared before reporting starts. The right choice is the model whose data requirements and accounting purpose the organization can support.
Showback before chargeback, and how to know when to make the switch
Showback presents attributed costs without posting them to departmental budgets. Chargeback turns the allocation into an accounting transaction. The FinOps Foundation states that neither approach is more mature than the other. Where costs already land on one or a few cost centers, permanent showback can be the appropriate answer.
Starting with showback nevertheless has a practical advantage. Finance must agree on a chargeback methodology and secure team-lead support before enforcing it, whereas showback can be established in weeks. It lets teams check who owns the costs, what the rates are, and how shared costs are handled before those choices affect their budgets. A reporting correction is less costly to resolve than a billing dispute, particularly when the dispute is the first serious examination of the data.
The gate to chargeback is therefore allocation accuracy. Run showback until teams stop disputing the numbers, then bill only the allocation that survives that scrutiny. Pressure to share out a growing central AI budget leaves the gaps in attribution just as hard to trust. Premature chargeback can also discourage experimentation before there is enough usage history to calibrate unit economics.
Showback can remain in place for shared costs while direct costs are charged back, or it can remain the sole approach. The practical decision belongs with the controller. Ask whether the finance function requires the allocation to be posted, rather than whether the FinOps practice is ready to graduate.
How to stop AI coding agents from running up unexpected API bills mid-session
Reporting and enforcement answer different questions. A chargeback report identifies who spent the money, while a session-level cap constrains whether an agent can keep spending it. An autonomous retry chain can accumulate costs before a batch reporting cycle exposes the problem. An alert after that chain finishes is not a hard limit.
The enforcement stack therefore needs hard caps at the session, developer, and time-period levels. The session ceiling bounds an individual run regardless of its duration or retry count, while the broader limits constrain accumulated use. Anomaly detection adds a rolling baseline to spot spend that is out of the ordinary. It must also account for pricing changes, because a provider can change the bill without any change to code or usage patterns.
Ellipsis, a managed cloud platform for running Claude Code and Codex agents, enforces spend limits before a session continues. Its hard caps operate at the session, agent, and developer levels, with tool-call and token logs in the same system. Sessions run in isolated sandboxes with credentials minted for the run and revoked on completion. For platform evaluation, blocking further execution at the ceiling is the concrete distinction between enforcement and reporting. That distinction does not, by itself, establish how a graceful shutdown handles unfinished work.
Between reporting cycles, model routing offers the most control over costs. Directing most queries to a budget-tier model rather than a flagship model changes effective spend without changing the allocation method. Put those routing decisions in version-controlled agent configuration so that cost policy can be reviewed, audited, and rolled back.
Governance requirements that make an allocation model defensible to finance, security, and compliance
A defensible allocation must reconstruct which agent acted, under whose authorization, and on behalf of which team. The record covers model output as well as tool calls, subagent delegations, and real-world actions. That chain is needed to show who had the authority to spend the money in a cost total. MAGE frames this as an authority problem, requiring constraints, sensors, validators, and gates rather than relying only on static IAM rules and after-the-fact logs.
Agent identity supplies the foundation for that record. Each cost event must point to a specific agent acting under a specific authorization. Session-scoped credentials support accountability by being minted for each run and revoked on completion. They are not the whole identity model, however, because unambiguous identity additionally requires per-instance cryptographic identities and mutual agent-to-agent authentication.
Configuration supplies the other structural requirement. Prompt changes, guardrail updates, and routing revisions should carry a diff, an author, an approval signature, and a deploy timestamp. In Spec-Driven Development for Agentic Software Engineering, specifications that spell out the requirements and are version-controlled form the contract between humans and agents. Repository-based YAML definitions in Ellipsis apply that configuration-as-code pattern, placing agent policy under code review and versioning.
The minimum viable architecture brings these requirements together through a tagging gateway, verifiable agent identity, session-level enforcement, version-controlled policy, and an action record tied to ownership. Each part supports a different audit question. Together, they make the allocation explainable as an authorized chain of activity.
How to roll out the framework in practice — and what breaks first
Rollout usually becomes harder as it moves from collecting data to agreeing on allocation and sustaining enforcement. The first phase establishes call-time tagging and the four-tier hierarchy. That phase is complete only when every agent call carries the full ownership chain. Direct provider SDK calls are the first gap to close because they bypass attribution at its source.
Before the first showback report, agree in writing on the shared-cost rule, the treatment of the unallocated residual, and the boundary between central and charged costs. Then run showback until attribution disputes fall to near zero. Shared-cost disagreements should stay visible in the residual line. Changing allocation rules retroactively after teams have seen their numbers is a trust problem.
Introduce hard caps and anomaly detection after that validation, and before deciding with the controller whether chargeback is required. The cap phase is complete when no session can exceed its ceiling without a policy override. Keeping that test separate from the accounting decision makes clear that showback still comes with limits on spending. It also avoids using premature chargeback as a substitute for runtime control.
Routing policies and guardrails kept outside version control can change without review, leaving no policy history that can be audited alongside the cost record. Agents-as-code prevents that split from the start. Configuration checked into the repository, reviewed, and versioned keeps governance and cost attribution in the same durable process.