Pricing Models for Managed AI Coding Agent Platforms
Hard spending limits matter more than the pricing model itself.
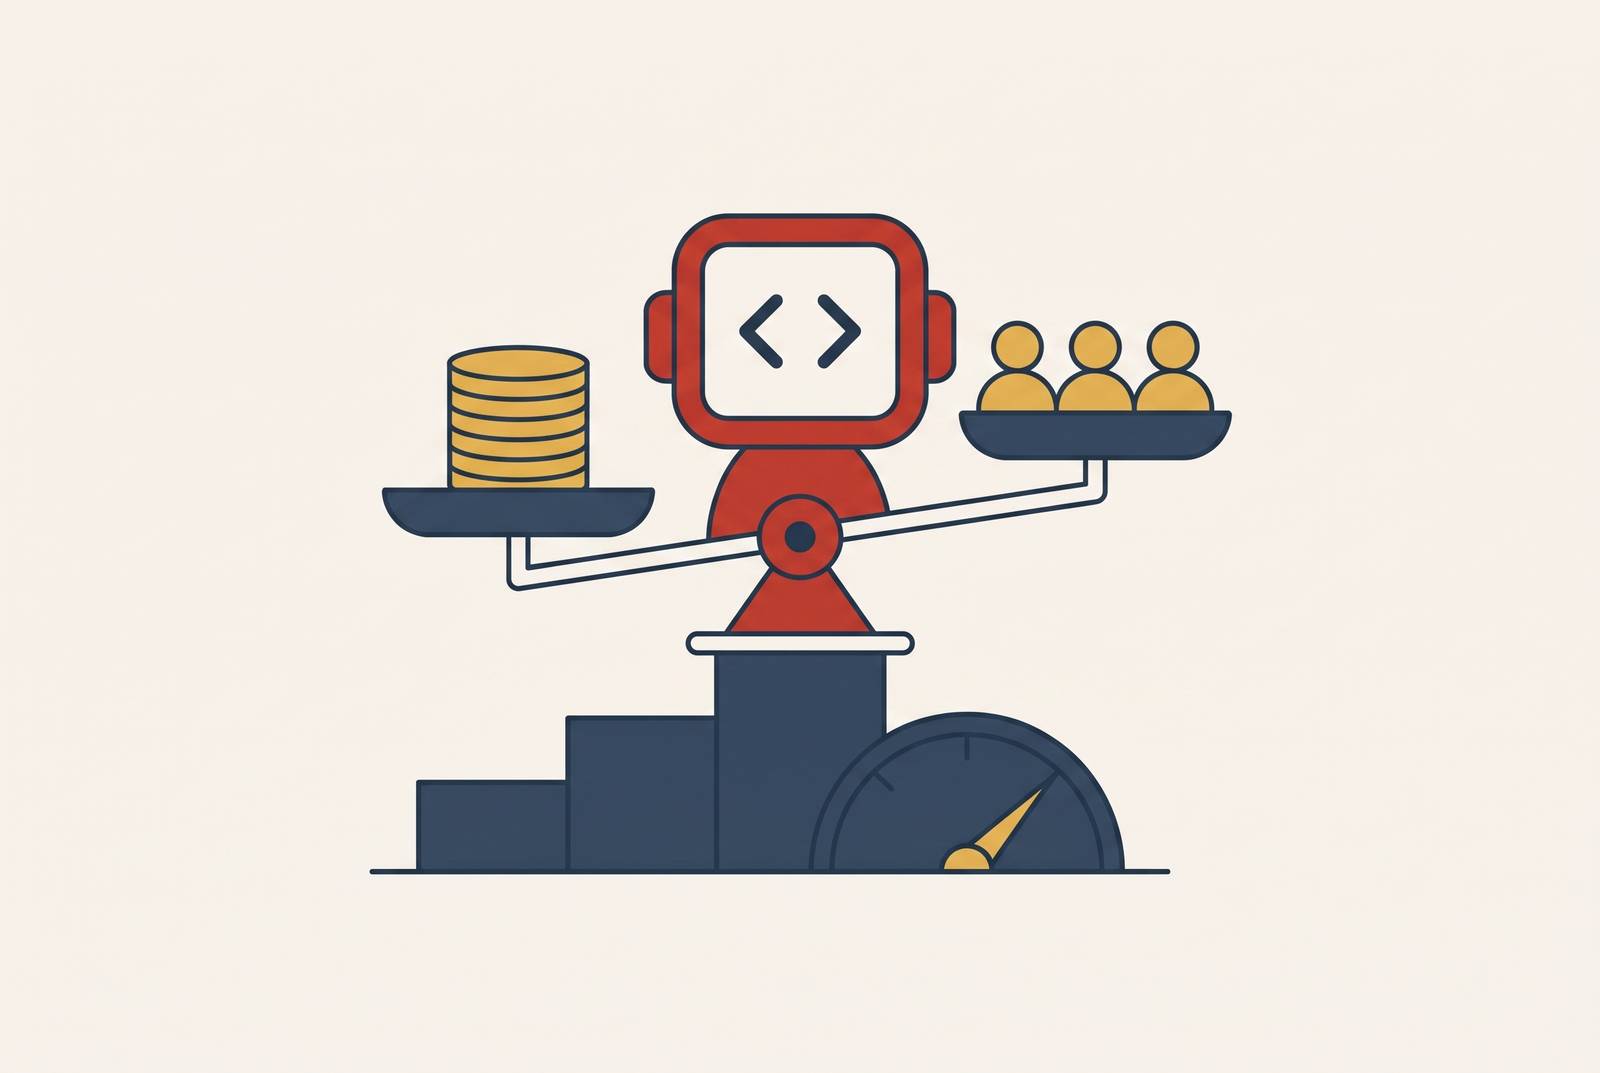
Managed AI coding agent pricing constrains budgeting and governance for autonomous work in production. To avoid unexpected API bills, a team needs a platform layer that enforces hard spending limits for each session, developer, and time period before more money is spent. Seat, token, and effort-based billing each charge for a different resource, but none includes that control by default. A spending report is not an execution stop.
Why pricing structure determines whether agents reach production
Pricing architecture is an operational constraint. Here, pricing means the rules governing when and how costs arise, including allowance consumption, quota boundaries, and overage behavior. The listed price is only one component. Those rules govern a team’s ability to attribute spending to particular work, constrain autonomous execution, and expand deployment without losing budget control.
That constraint becomes more significant when software acts autonomously. Earlier developer tools supported human-paced interactions, while agents reason through sustained workflows, invoke tools, and iterate without requiring a person to authorize every step. Execution can outlast the initial request by a considerable margin. Consequently, model quality alone does not establish production viability, because escalating costs, unclear business value, and inadequate risk controls can prevent a capable agent from becoming an operational service.
The three billing architectures and what each one actually charges for
Seat-based subscriptions charge a fixed monthly amount with a bundled allowance. OpenAI Codex offers Free, Go, Plus, and Pro tiers at ascending monthly prices, with ChatGPT Work and Codex sharing plan usage. Business is priced per user per month on an annual basis for two or more users. Further use is paid for through Codex Credits or a separate API-key route billed at API rates. The subscription and the overage route are distinct.
Token-based billing charges for how much of the model is used. Open-source agents that use bring-your-own-API-key, or BYOK, work this way because the tool is free and the model provider’s token rates set the bill. Multiple parallel sessions are unrestricted by the tool’s subscription structure, while cost monitoring falls to the team. Usage, rather than access, is the billing unit. For heavy Claude Code use, Max subscription tiers can be substantially cheaper than raw API billing, illustrating how workload changes the comparison.
Devin’s ACU structure exemplifies charging for completed autonomous work. That shifts the accounting unit toward task effort. It does not make all tasks equivalent, because different tasks and codebases require different amounts of effort. These three architectures therefore describe what is purchased.
How seat-based pricing breaks down when agents parallelize
Per-seat pricing maps costs to people, while agent parallelism separates the volume of work from the number of people initiating it. That mismatch creates a structural disincentive to parallel execution. A developer can initiate several autonomous workflows, but a seat’s bundled allowance does not become larger simply because more workflows run concurrently. The productivity case and the purchasing unit diverge.
Shared credit pools make that divergence operationally visible. Chat, agent mode, and CLI use can draw from the same allowance, so heavy autonomous work competes with other activity for bundled capacity. Autocomplete-only use does not create the same sustained demand. Although the monthly subscription is known, the seat price alone does not reveal which run consumed which share of the pool or provide a session-level spending boundary.
Temporary promotional credits can make early usage appear affordable until those credits expire, leaving teams with budgets calibrated to a temporary allowance. Bundling also skews the price when buying an agent seat means paying for another enterprise tier. The headline figure then understates the purchase required. Together, these constraints make seat pricing predictable as an access charge but insufficient as a model of parallel workload cost.
How token-based billing breaks down when agents run long or loop
Token billing removes the seat-based disincentive to parallelism, but it exchanges that constraint for exposure to continuing consumption. A long refactoring session can consume tokens equivalent to many times a typical seat’s monthly allowance. A looping agent can spend without human intervention.
Token billing by itself does not impose the session-level or developer-level limits required to govern agent work, so the platform or team must supply those controls. Monitoring alone is insufficient for that purpose. A light day and a large refactor can have sharply different costs, making monthly forecasts unreliable when nothing constrains individual runs.
Different harnesses can produce different results with the same model, so model selection is not the only cost variable. Configuration offers another source of efficiency. Research on arXiv associates an AGENTS.md file with a 28.64% reduction in median runtime and reduced output token consumption while maintaining comparable task completion. However, that intervention improves a functioning run rather than capping or halting a malfunctioning one, so prompt efficiency cannot substitute for enforcement.
Why effort-based ACU pricing solves some problems and introduces others
Effort-based pricing loosens the connection between cost, seat count, and raw token consumption. Its appeal is a billing unit closer to autonomous work than to the machinery producing it. That is a genuine change in accounting. However, effort per task varies across requests and codebases, so a team still cannot infer a stable task price merely from the existence of an ACU rate.
Quota boundaries create another form of interruption. Daily and weekly quotas on lower tiers can rate-limit an agent mid-task even when the team has the budget for more work. On-demand credits that roll over and do not expire address unused budget while leaving real-time attribution of credit consumption to tasks unresolved.
The model also has a portability constraint. Effort-based pricing is typically confined to a vendor’s own agent rather than serving as a common billing unit across multiple agents and models. A mixed deployment still needs a shared accounting layer. ACUs can simplify the connection between a bill and autonomous effort, but they exchange token-level uncertainty for task-effort uncertainty, leaving budget variance in place.
What governance actually requires from a billing architecture
To govern agents in production, a team needs a stack of controls above the billing unit. Its first tier is enforceable spending limits at the session, developer, and time-period levels, with decisions made before further spend occurs. Aggregate monthly reporting cannot fulfill that requirement. A platform must distinguish a hard stop from throttling or paid overage, because those responses have different consequences for both budget and task completion.
A second tier constrains what execution may do. Seven primitives belong at platform level, namely audit logs, policy enforcement, rate limits, depth and recursion bounds, role-based access control, human-in-the-loop approvals, and cost ceilings. They must apply consistently across tools and models. Recursion bounds and rate limits control how execution behaves, while a spending cap limits how much it can cost.
A third tier protects the execution environment and supports accountability. Sandboxing with credentials minted per session and revoked on completion addresses the risk of credentials persisting across runs. That protection is separate from the billing model. Enterprise deployment also requires SSO integration, audit logging connected to a security monitoring system, secret scanning on agent PRs, PR policy gates, license governance, sandbox isolation, and incident response runbooks. A subscription tier alone cannot provide all these controls over cost, access, and operations.
Why a managed platform layer above the billing model is the production answer
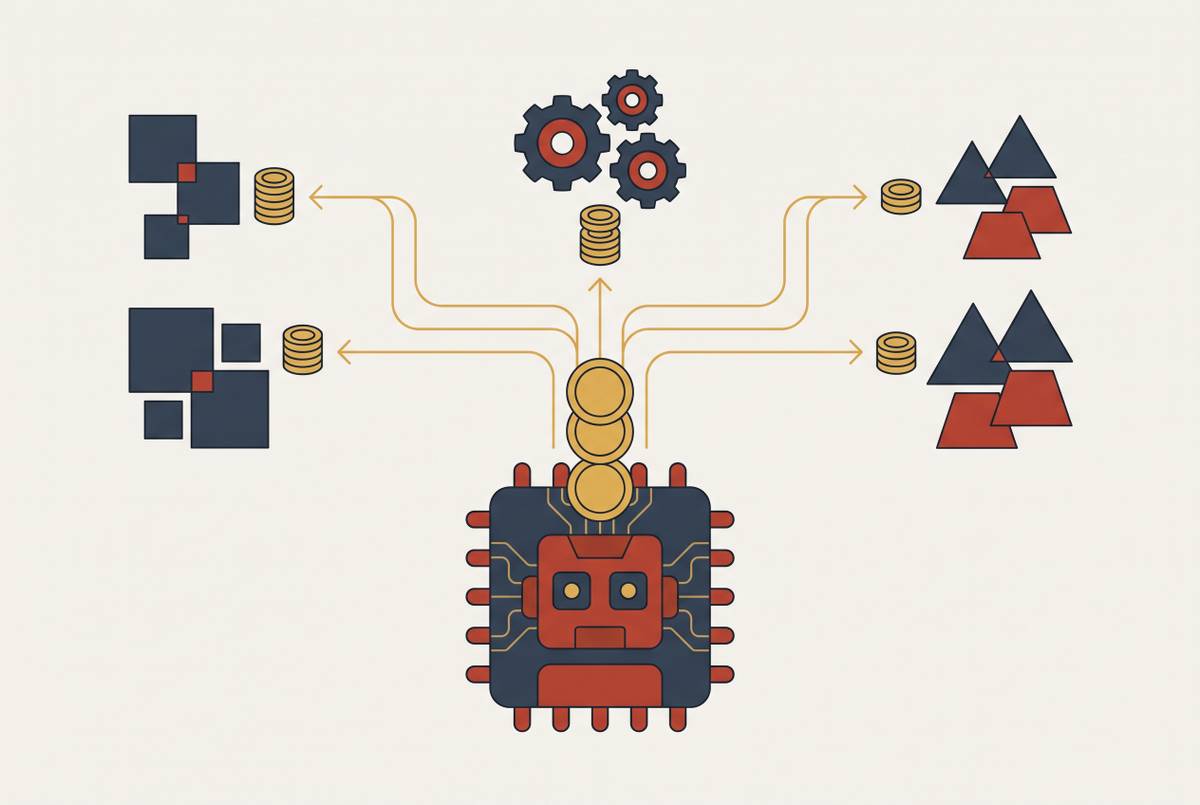
A team using multiple agents and models needs one place to apply policy consistently. Billing controls from each vendor cannot govern the whole deployment on their own. A managed infrastructure layer gives the team one place to enforce rules across seat allowances, token charges, and effort credits. This separates the choice of agent from the requirement that every agent operate within the same spending and security boundaries.
Hosting economics do not remove that requirement. At typical usage, self-hosted inference becomes cost-effective only when the number of developers passes a threshold, while managed API billing is cheaper below that threshold because paying for actual use avoids the cost of reserved compute. Neither arrangement includes governance by default. A hybrid architecture can send large numbers of simple tasks to self-hosted inference and complex tasks to managed APIs, cutting managed API costs while keeping quality high for demanding work. It still requires a control plane that applies policy across both environments.
Agent configuration belongs within that control plane’s governance model. Defining behavior in YAML files checked into the repository gives configuration the version control, review, and audit discipline already applied to code. Changes become reviewable rather than merely adjustable. This agents-as-code approach complements runtime controls, because approved configuration and enforced execution boundaries address different parts of the deployment.
Running Claude Code or Codex on a laptop or bare VM demonstrates that an agent can execute work. It does not establish the required governance boundary. Managed infrastructure with scoped credentials, budget enforcement, and full audit trails supplies that boundary regardless of whether the underlying work is billed per seat, per token, or per ACU.
How to evaluate a managed agent platform's billing architecture before committing
The evaluation should start with the subscription or seat charge. A team should check whether the listed price covers what it needs for a usable deployment, including any bundled product tier. The team should include the minimum team size in that calculation. It should also check whether costs rise linearly as developers join or jump at certain points, because those rules set the cost of getting started and growing the team.
The next layer is the included allowance. Evaluation should establish whether it resets monthly, weekly, or daily and whether chat, agent mode, CLI, and API activity share a pool. Model choice may also change the consumption rate. Real-time visibility into those differences is necessary to distinguish an allowance that fits the workload from one that merely looks generous before sustained execution begins.
Overage behavior is the decisive third layer. A team should establish whether exhaustion stops execution, throttles it, or starts additional charges, and whether session-level and developer-level caps apply before overage is incurred. For buyers seeking budget cap enforcement and graceful shutdown, the evaluation must separate the financial guarantee that spending halts from the operational question of how interrupted work is handled. A quota label alone answers neither question adequately.
The governance assessment then extends beyond the pricing page. A team should require attribution of every tool call, diff, and token to a person or trigger, together with per-session credentials revoked on completion. Configuration should be version-controlled and reviewable through the same workflow as code. The notes do not show that any named platform supports all these controls, so its pricing architecture alone is no basis for claiming that it does.
Self-hosting is warranted by hard data-residency requirements, a physical-custody compliance mandate, a need to pin or fine-tune the model, or an infrastructure team with existing capacity. Otherwise, managed infrastructure with governance is the default choice on cost and velocity grounds. The commitment is not simply to a rate card, but to the rules under which autonomous work may continue.